Book A Meeting
SMC Consulting
HaloITSM problem management

ITIL problem management in HaloITSM, set up by ITIL v4 consultants

Incident management restores service; ITIL problem management makes sure the same incident stops coming back. SMC Consulting's ITIL v4 certified consultants set up problem management in HaloITSM: recurring incidents grouped into problems, root causes investigated with a method, known errors and workarounds published to agents, and permanent fixes raised as changes.

180ITSM implementations
40+ITSM migrations
20years in IT service management
Illustration of ITIL problem management: a magnifying glass finds the root cause behind repeated incidents
SMC Consulting

They trust us on their ITSM projects

  • Proximus
  • Lineas
  • Brussels Airport
  • ING
  • CPH Banque
  • DKV
  • Loterie Nationale
  • Crelan
  • Belfius
  • ALD Automotive
  • BNP Paribas Fortis
  • AXA
  • KBC

What is problem management in ITIL 4?

Problem management is the ITIL 4 practice that reduces the likelihood and impact of incidents by finding their causes, managing workarounds and known errors, and getting the causes removed. Its objective is fewer repeat incidents and shorter outages when they do happen.

It works in two ways. Reactive problem management starts from incidents that already happened, often a major incident or the same ticket seen ten times. Proactive problem management looks at trends, events and weak signals to remove a cause before it hurts anyone.

IncidentProblemKnown error
What it isAn unplanned interruption or reduction in the quality of a serviceThe cause, or potential cause, of one or more incidentsA problem that has been analysed but not yet resolved, usually with a documented workaround
GoalRestore service as fast as possibleFind and remove the causeHelp agents resolve the next occurrence fast, until the fix is in
OwnerThe service desk and support teamsA problem manager or problem ownerProblem management, published for the service desk
Ends whenThe user can work againThe cause is removed, usually by a changeThe permanent fix is in place

The ITIL practices and how they fit together are explained in the ITIL processes explained and in our practical guide to ITSM; for the incident side, see incident management in ITIL 4. HaloITSM is the tool we recommend most often to run both.

Source: the ITIL 4 Problem Management practice, ITIL 4 by PeopleCert.

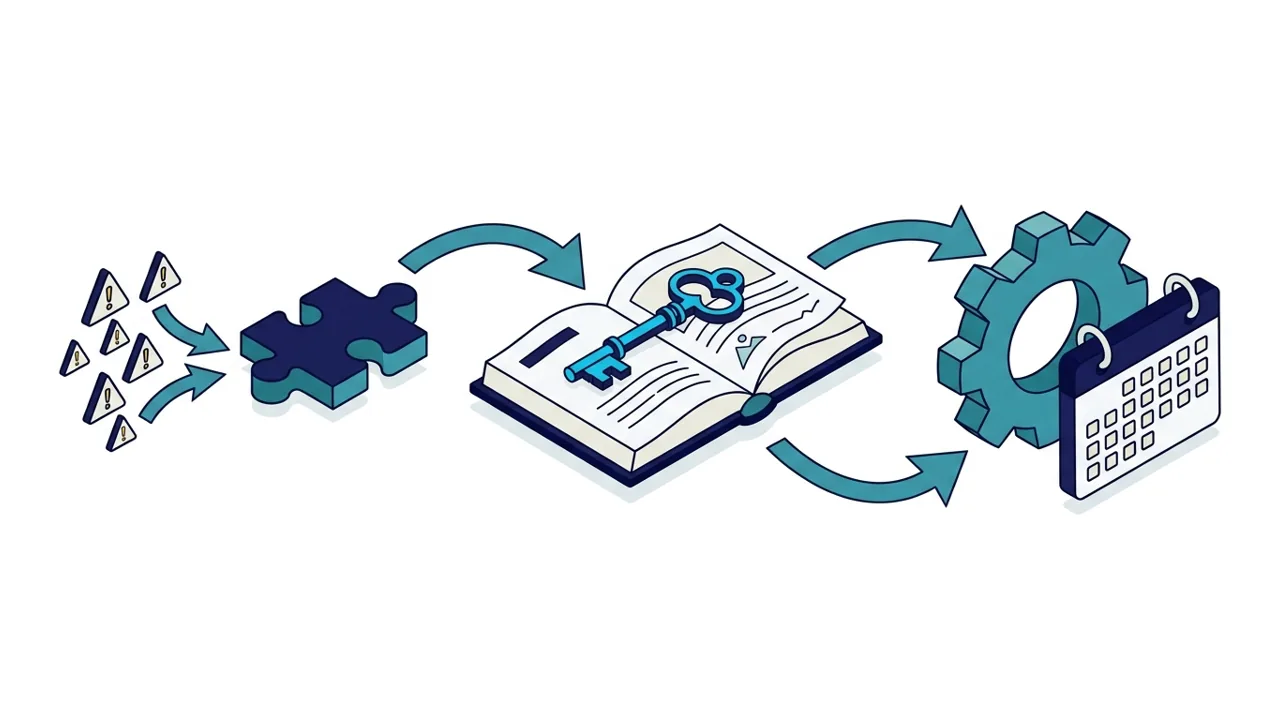
Flow diagram from incidents to a problem, a known error record and a change

The three phases: identification, control, error control

Problem identification

In HaloITSM, agents link related incidents and raise a problem from them; trend reports show the repeat incidents nobody flagged.

Problem control

The problem record holds the investigation: affected services and CIs, analysis, workaround and the people working on it. Once analysed, the problem becomes a known error.

Error control

Known errors are managed: workarounds kept current, and the permanent fix assessed and raised as a change when justified.

Proactive reviews

A monthly look at the top incident categories and services finds problems before the next major incident does.

See a problem go from repeat incidents to a fix in HaloITSM

A live demo on one of your recurring incidents, or a free trial: 30 days, 15 of them guided by SMC Consulting.

Root cause analysis methods, and where they live in HaloITSM

The method matters less than using one. We add a root cause section to the problem form so the analysis is recorded, not just discussed.

5 whys

Ask why until you reach a cause you can act on. Fast, good for most problems; recorded as a short chain on the problem.

Ishikawa (fishbone)

Causes grouped by category (people, process, technology, suppliers) when several factors combine; the diagram is attached to the problem.

Kepner-Tregoe

A structured comparison of what is and is not affected, for complex technical problems; the analysis steps become problem tasks.

The known error database (KEDB) in HaloITSM

Known errors with workarounds

Each known error records the symptoms, the cause when known and the workaround agents can apply today.

Published to agents

Known errors are suggested on matching incidents, so the second occurrence takes minutes, not hours.

Published to the portal

When the workaround is safe for users, it becomes a knowledge article in the self-service portal.

Self-service in HaloITSM

How SMC Consulting sets it up

Five steps, in Belgium, Luxembourg and France.

Not sure where your problem management stands today? Book my free ITSM audit: 30 minutes with a senior consultant. Still choosing a tool? Our comparison of the 10 best ITSM tools sets HaloITSM against the alternatives.

  1. Free ITSM audit

    Your repeat incidents, your major incidents of the last months, and who looks at causes today.

  2. Design

    Problem states, the problem form with its root cause section, known error records and the link rules to incidents and changes.

  3. Configuration and integrations

    Built in HaloITSM, with Jira or Azure DevOps sync for engineering and Teams notifications.

  4. First problems, worked with you

    Two or three real problems taken through the process with your team, from identification to the change.

  5. Proactive rhythm

    A monthly trend review in place, the KPIs below on a dashboard, and a review at six months.

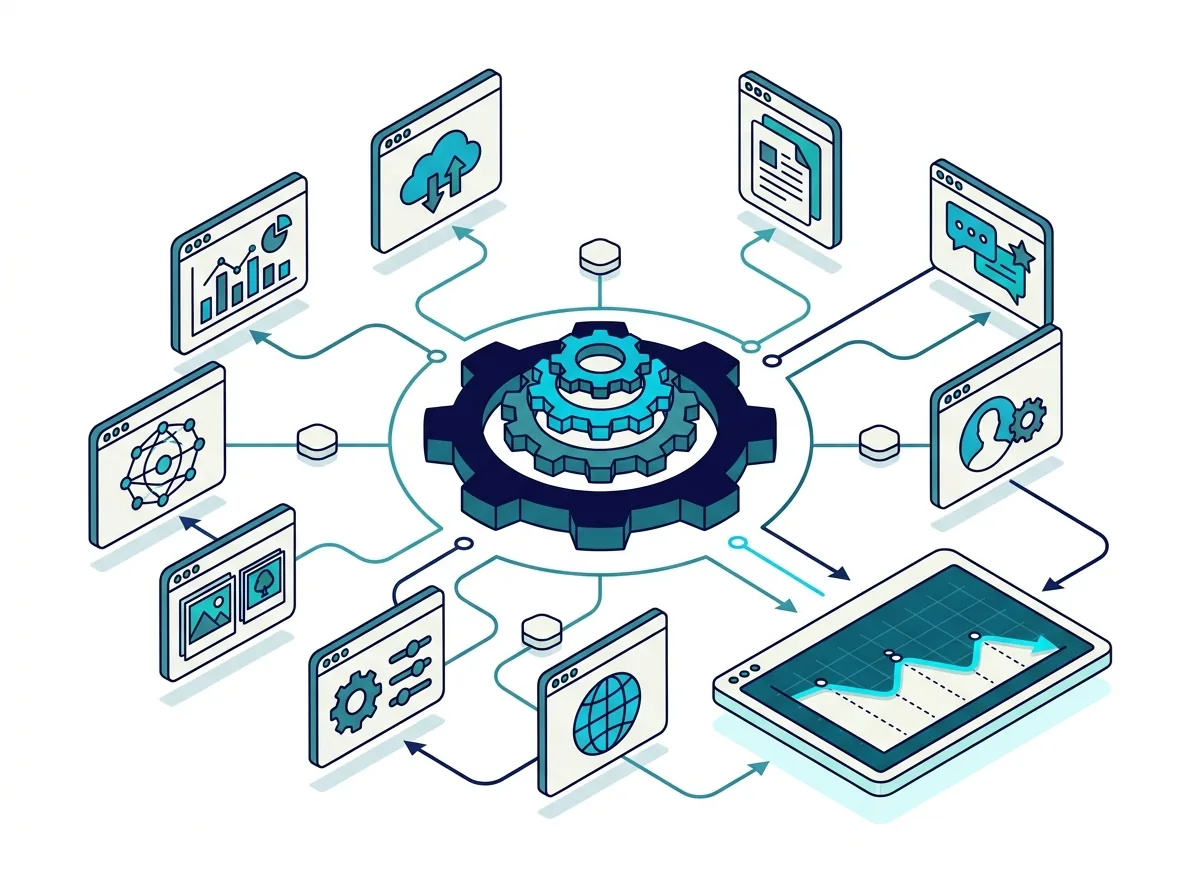
Connected applications around a central hub and a dashboard with a falling incident trend

Integrations and KPIs we set up

  • Jira and Azure DevOps: problem tasks synced with the engineering backlog, both ways
  • Microsoft Teams: problem owners and stakeholders notified where they work
  • Repeat incidents: incidents with the same cause, by service and CI, the number problem management exists to lower
  • Time to root cause: from problem creation to a documented cause
  • Problems with a known error: the share of open problems that already give agents a workaround
  • Problem backlog age: open problems by age, so none is forgotten

Linking problems to incidents, changes and the CMDB

Incidents

Incidents are linked to the problem, and closed together when the fix is in.

Incident management in HaloITSM

Changes

The permanent fix is raised as a change from the problem, assessed and approved like any other.

Change management in HaloITSM

The CMDB

Affected services and configuration items show which part of the estate keeps failing.

CMDB in HaloITSM

Who this is for

Service desk managers

Whose agents solve the same incident every week without anyone fixing the cause.

IT operations and infrastructure leads

Who need major incidents analysed and fixed, not just closed.

Major incidents in HaloITSM

Small IT teams

Who cannot staff a problem manager but can run a monthly review with the right tool.

ITIL problem management in HaloITSM: frequently asked questions

What is problem management in ITIL?

Problem management is the ITIL 4 practice that finds and removes the causes of incidents. It manages workarounds and known errors while the permanent fix is prepared, and it works both reactively, from incidents, and proactively, from trends.

What is the objective of problem management?

To reduce the likelihood and impact of incidents: fewer repeat incidents, shorter outages thanks to known workarounds, and permanent fixes delivered through change management.

What is the difference between an incident and a problem?

An incident is an interruption to restore now; a problem is the cause behind one or more incidents. The incident is closed when the user can work again; the problem stays open until its cause is removed. See incident management in ITIL 4.

What is a known error database (KEDB)?

The collection of known errors: problems that have been analysed but not yet resolved, with their cause when known and their workaround. In HaloITSM, known errors are suggested on matching incidents, so agents apply the workaround straight away while the permanent fix is on its way.

Who owns problem management in a small IT team?

Often the service desk lead or an infrastructure engineer, a few hours a month. What matters is one named owner, a monthly review of repeat incidents, and a tool that keeps the links between incidents, problems and changes.

Can HaloITSM link problems to Jira or Azure DevOps?

Yes. When the fix needs development work, problem tasks are synced with Jira issues or Azure DevOps work items, so the status stays the same on both sides without copying updates by hand.

Stop the same incidents coming back, with HaloITSM

Book a live demo on one of your own recurring incidents. You can also start a free trial: 30 days, 15 of them guided by SMC Consulting.